Two models of node autoscaling
The Kubernetes documentation describes node autoscaling as provisioning nodes when pods cannot be scheduled and consolidating them when they are underused, and lists two autoscalers sponsored by SIG Autoscaling: Cluster Autoscaler and Karpenter1. They solve the same problem from opposite ends.
Cluster Autoscaler works with node groups you define in advance: a group of one machine type, another for GPUs, perhaps a Spot group. When pods are pending, it grows the group whose nodes would fit them; when nodes are underused, it shrinks groups. Your choices about machine types are made up front, in the groups.
Karpenter starts from the pods. It reads what pending pods need, chooses machines to fit them within the limits you set in NodePools, launches them directly and manages their whole lifecycle, including replacing and consolidating them later1. Your choices are expressed as constraints rather than fixed groups.
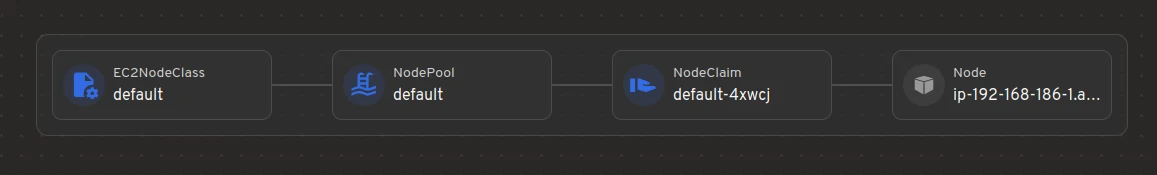
How a scale-up differs
- Pods pending
- Simulate which node group would fit
- Increase that group's size
- Cloud group launches its fixed machine type
- Pods pending
- Batch and read their requirements
- Choose machine types within NodePool limits
- Launch nodes directly as NodeClaims
The practical consequence is flexibility. With Cluster Autoscaler, a workload that needs an unusual shape needs a node group that already offers it. With Karpenter, it needs a NodePool whose constraints allow it. That is why Karpenter tends to suit mixed and changing workloads, and why it needs firmer guard rails: a loose NodePool can launch machine types you never tested.
Scale-down is where the real difference is
Scale-up gets the attention, but cost is decided on the way down. Karpenter's disruption controls cover consolidation, which removes or replaces underused nodes with cheaper ones, as well as drift, when a node no longer matches its configuration, and expiry after a set lifetime2. Disruption budgets limit how many nodes can be disrupted at once and can be scheduled, so you can, for example, allow consolidation only outside business hours4.
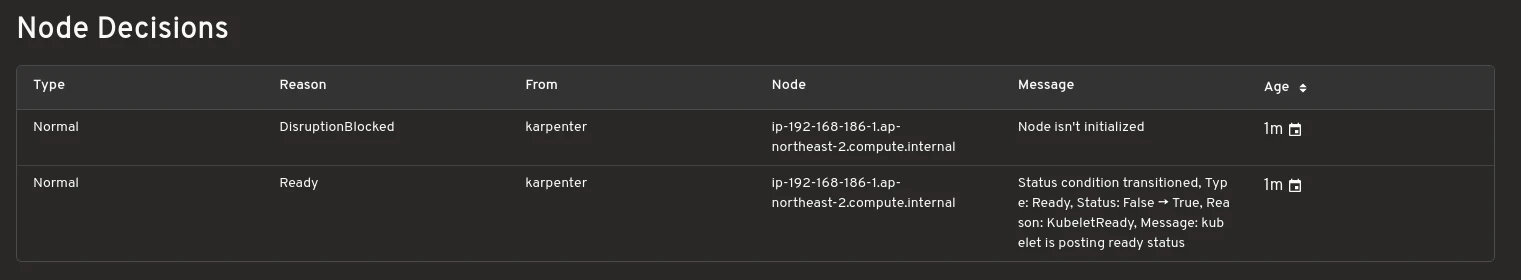
That power has a cost: pods get moved more often. Workloads without pod disruption budgets, with long start-up times or with local state will feel it. The Headlamp plugin for Karpenter surfaces these scaling and disruption decisions in a UI6, and the view below shows the other side: a node whose disruption was blocked, which is what you want for a protected workload and what you need to notice when it stops consolidation entirely.
Managed options change the question
You may not have to run either yourself. AKS node auto-provisioning provisions and manages virtual machines in response to pending pods using Karpenter, configured through NodePools and AKS-specific node classes3. EKS Auto Mode manages compute for you and replaces nodes after a maximum lifetime of 21 days, which you can shorten5.
Managed versions remove the work of running the autoscaler, but they also make choices for you: node images, lifetimes and which settings you can change. Read the limitations pages before committing, especially if you need particular operating systems, network modes or access to nodes.
Side by side
| Question | Cluster Autoscaler | Karpenter |
|---|---|---|
| What you define | Node groups with fixed machine types | NodePools with constraints and limits |
| Scale-up decision | Which group to grow | Which machines to launch |
| Scale-down | Remove underused nodes from groups | Consolidate, replace, handle drift and expiry |
| Predictability | High: only the shapes you listed | Depends on how tight your constraints are |
| Workload churn | Lower | Higher unless budgets are tuned |
| Best fit | Stable fleets, pinned GPU pools, platforms without a Karpenter provider | Mixed or bursty workloads, Spot, cost-sensitive fleets |
How I decide
- ProviderIs there a supported Karpenter provider or a managed option on your cloud?
- WorkloadsAre they varied and bursty, or a few stable shapes?
- ToleranceCan they be moved: PDBs, fast start-up, no local state?
- AcceleratorsDo GPU pools need to stay pinned and warm?
- OperationsWho will own NodePools, budgets and upgrades?
- PilotMove one non-critical workload class first and compare cost and disruption
If your workloads cannot tolerate being moved, Karpenter's main advantage turns into a source of incidents. Fix disruption tolerance first, then change autoscaler.
For AI workloads, I often run both patterns: Karpenter for general and bursty services, and pinned, separately managed GPU capacity where warm nodes and scarce accelerators matter more than consolidation. See GPU scheduling with DRA, scale to zero, AI cost allocation and the Kubernetes FinOps case study.
If you are deciding how to run Kubernetes capacity for AI and product workloads, I am a fractional CTO and AI architect based in India, the United States and the UAE, working globally. You can analyse your challenge and bring the result to a call.
- 1Node AutoscalingKubernetes documentation
- 2DisruptionKarpenter documentation
- 3Node auto-provisioning overviewMicrosoft Learn
- 4Node auto-provisioning disruption policiesMicrosoft Learn
- 5Automate cluster infrastructure with EKS Auto ModeAmazon EKS User Guide
- 6Introducing Headlamp Plugin for Karpenter: Scaling and VisibilityKubernetes blog (René Dudfield, Anirban Singha) · 6 Oct 2025