What happened
Microsoft is winding down a 2023 arrangement to rent AI computing capacity from Oracle and did not renew it, The Next Web reports, citing Bloomberg; the capacity reportedly ran on older-generation Nvidia chips that no longer met Microsoft's needs1. Oracle responded that demand for its AI infrastructure remains strong, including for earlier-generation GPUs1. Both statements can be true, and the gap between them is the useful lesson: a GPU can be obsolete for one buyer's workload and perfectly good for another's.
How fast do AI chips age?
Nobody agrees. Large cloud companies depreciate servers over roughly five to six years, while some critics argue the real useful life of AI chips is two to three years and that profits are overstated as a result2. Others argue that older GPUs "cascade" to less demanding work, so long accounting lives bend rather than break3. Amazon moved the other way from its peers in 2025, shortening the assumed life of a subset of servers from six years to five and citing the pace of AI and machine learning development4.
For a buyer, the accounting debate matters less than a simpler distinction: a chip has a physical life, how long it keeps working, and an economic life for a given workload, how long it stays the cheapest way to do that job. Economic life is short for frontier training and large-model serving, and much longer for smaller models, embeddings and batch work.
- Training
- Largest models
- Latency-critical serving
- Mid-sized models
- Fine-tuning
- Most production inference
- Small and quantised models
- Embeddings and batch jobs
- Evaluation runs
- Cost per output too high
- Power better spent elsewhere
- Support ends
What this means for capacity contracts
Most companies do not rent AI capacity at Microsoft's scale, but many now sign reserved GPU commitments with cloud providers or specialist GPU clouds. The terms that matter most are the ones that protect you when a generation ages faster than expected.
| Term | Risky version | Safer version |
|---|---|---|
| Length | Longer than the chip's economic life for your workload | Matched to that life, with renewal options |
| Hardware | Fixed to one named generation | Right to move to newer generations on agreed terms |
| Price | Per GPU-hour only | Per GPU-hour with a path to performance-based or per-output pricing |
| Flexibility | Fixed region and volume | Ability to shift between regions and step volume up or down |
| Exit | No break clause | Defined exit or conversion terms |
Providers will not offer all of these, and each one costs something. The point is to price the risk deliberately rather than discover it in year three. See planning around the AI capacity crunch and AI cost allocation.
The architecture that keeps you free to move
Contract rights are only useful if your workloads can actually move. Four habits make that cheap:
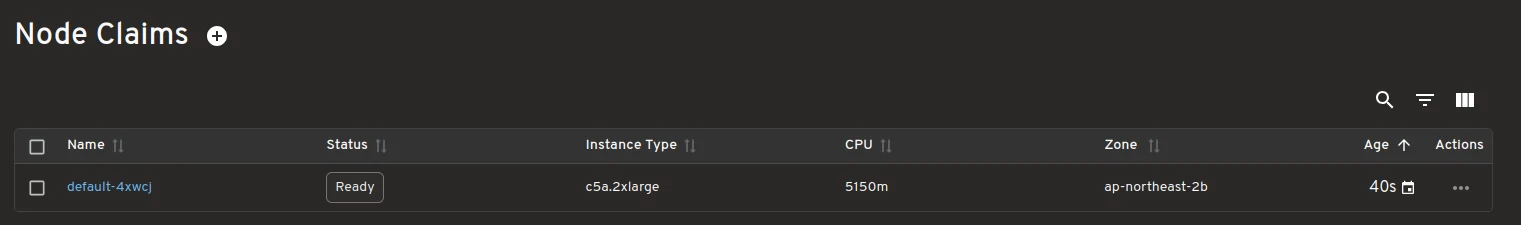
- Ask for capabilities, not machines. Describe what a workload needs (memory, accelerator type, zone) and let the platform pick the hardware. Kubernetes node provisioners such as Karpenter choose instance types from requirements, so changing hardware becomes a configuration change5.
- Route by task. Put a gateway between product features and models, so a task can move to a different model, size or provider without code changes; see model routing.
- Make models fit older hardware. Quantised and smaller models extend the economic life of older GPUs for many tasks, if your evaluations confirm the quality holds.
- Evaluate per generation. Run the same evaluation set on each hardware and model combination before moving traffic; see evaluation sets that predict production.
Buy GPU capacity the way you would buy any fast-depreciating asset: short enough to stay current, flexible enough to move, and with workloads designed to use whatever generation is cheapest for the job.
Who should act
- Companies with reserved GPU commitments: list each contract's term, hardware generation and exit terms against your workload mix.
- Companies about to sign: negotiate generation and region flexibility before price; it is worth more over the term.
- Teams running their own GPUs: plan how each generation moves down to cheaper work, rather than treating hardware as either current or scrap. See the multi-region AI capacity case study.
CTO take
Microsoft's decision is less a verdict on Oracle than a reminder that AI hardware has the economics of a fast-moving consumable, not a building. The buyers who do well will treat capacity as a portfolio: newest chips for the few workloads that need them, older ones for everything they can still do cheaply, and contracts and architecture that let work move between them as prices and needs change. Read alongside the 7 November tech news.
How I can help
I help companies plan AI capacity, review GPU and model contracts, and build platforms that move workloads between providers and hardware generations. I am based in India, the United States and the UAE, working globally. See AI architecture, where I work, or analyse your challenge and bring the result to a call.
- 1Microsoft is winding down its deal to rent AI computing from OracleThe Next Web · Nov 2026
- 2
- 3Resetting GPU depreciation: Why AI factories bend, but don't break, useful life assumptionsSiliconANGLE · 22 Nov 2025
- 4
- 5Introducing Headlamp Plugin for Karpenter: Scaling and VisibilityKubernetes blog · 6 Oct 2025