What was released
OpenAI released GPT-6.1 Terra on 26 October 2026, a mid-sized model aimed at computer use, visual reasoning and coding, available in ChatGPT and Codex2. Quartz reports API pricing of $1 per million input tokens and $5 per million output tokens, half the price of the models it sits below, along with benchmark gains that come from OpenAI's own testing1. Coverage of the cost per task compared with competing frontier models varies between outlets, from about nine to about twelve times lower34, which is a reminder that these are vendor-sourced comparisons, not independent results.
Why mid-tier releases matter more than frontier ones
Agents that operate software make many model calls per task: read the screen, decide, act, check, repeat. Most of those steps are routine. A capable, cheaper model in the middle tier changes the cost of the whole loop, while frontier models are only needed for the hard decisions. The architecture that benefits is one that already routes by step difficulty and measures cost per completed task.
More on the pattern in LLM model routing.
How to decide whether to switch
- BaselineMeasure current quality and cost per completed task, not per token
- ReplayRun your evaluation set and recorded tasks against the new model
- Compare by stepFind which step types match quality and which degrade
- RouteMove only the matching steps, behind a feature flag
- WatchTrack cost, latency and task success in production telemetry
- DecideKeep, widen or roll back based on your numbers, not the launch post
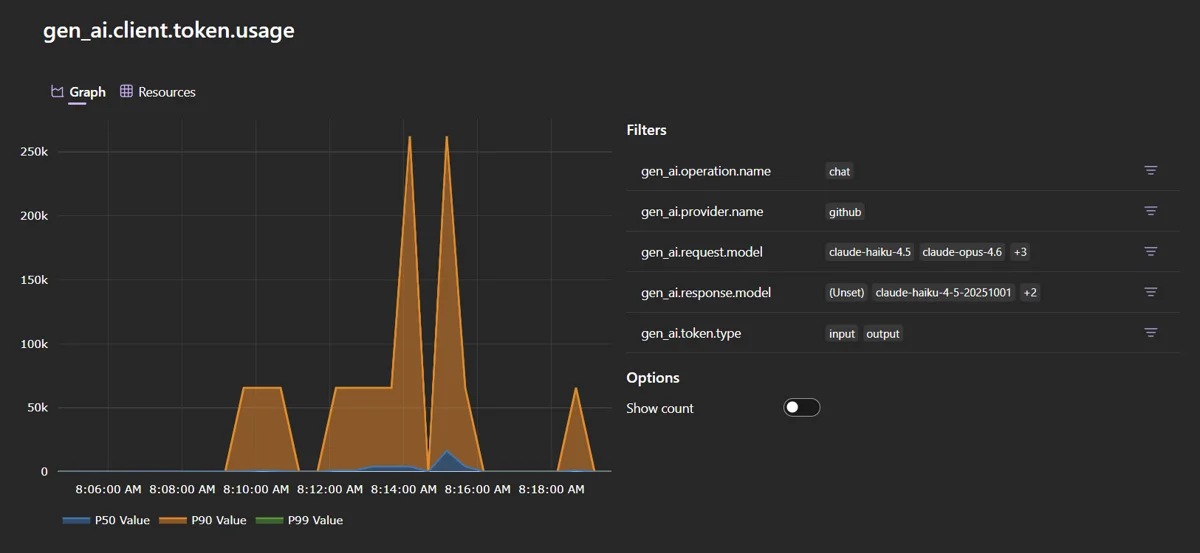
The measurement layer is where most teams fall short. OpenTelemetry's GenAI conventions record each model call with the requested model, token usage split into input and output, and latency, so you can compare models side by side and estimate cost per request5.
Price per token is a vendor's number. Cost per completed task is yours. Only the second one should drive a model switch.
Risks to price in
| Risk | Why it matters | Mitigation |
|---|---|---|
| Benchmarks that do not match your work | Vendor results use their tasks, not yours | Your own evaluation set per step type |
| Cheaper steps, more steps | A weaker model can loop longer and cost more per task | Budget guards and cost per completed task |
| Excessive agency | Computer-use agents act on real systems6 | Tool allowlists, sandboxing and approvals |
| Data location | Screens and files may hold personal or regulated data | Check region, retention and contract terms in each market |
| Single-vendor lock-in | Prices and models change quickly | A provider-neutral routing layer |
Sandboxing matters even more when agents get cheaper and run more often; see what Anthropic's S-1 teaches about sandboxing agents.
CTO take
Treat this release as a prompt to build the plumbing, not as a reason to switch. If you can already measure quality and cost per task by step type, a cheaper capable model is close to free money: route the routine steps and keep the hard ones where they are. If you cannot, the first job is the evaluation set and the telemetry. That is true whether your teams are in the US, Europe, India or Asia-Pacific; data-location rules differ by market, so check them before sending screens and documents to any new model (by region).
Related reading: evaluation sets that predict production, LLM observability with OpenTelemetry, evaluating AI agents and the daily tech news for 29 October.
How I can help
I design agent platforms with routing, evaluation and cost telemetry built in, so model launches become a measured decision rather than a gamble. See AI architecture, or analyse your challenge and bring the result to a call.
- 1OpenAI is launching cheaper mid-tier GPT-6.1 Terra for computer workQuartz · Oct 2026
- 2OpenAI upgrades ChatGPT and Codex with new GPT-6.1 Terra model9to5Mac · 26 Oct 2026
- 3OpenAI launches GPT-6.1 Terra with 3x faster AI agents, 50% lower pricingBleepingComputer · Oct 2026
- 4OpenAI launches GPT-6.1 Terra for precise computer useTestingCatalog · Oct 2026
- 5Inside the LLM Call: GenAI Observability with OpenTelemetryOpenTelemetry blog (James Newton-King) · 14 May 2026
- 6OWASP Top 10 for LLM ApplicationsOWASP GenAI Security Project