What happened
Problems began with Exchange Online and spread to other Microsoft 365 services and regions on 12 November. Microsoft's advisories listed Exchange Online, Teams, SharePoint Online, Microsoft 365 Copilot and Defender XDR among affected services, and users also reported OneDrive problems13. Microsoft said servers were failing automated health checks and dropping out of service, pushing load onto the rest, and that it had found no indication of malicious activity2. It paused deployments and worked on a configuration change to relieve an overwhelmed connection process3.
The disruption was felt worldwide, with users in Australia reporting problems into the next day4. Recovery was gradual and uneven, and Microsoft has promised a post-incident report with the root cause1. Business customers may be able to claim service credits, but generally need to ask5.
Why one outage reached so far
Most organisations no longer use a productivity suite only for email. Over a few years it has become the place where people talk, store documents, sign in, get AI help and often run security tooling. When it fails, the effects cascade.
The pattern is worth naming: the tools you use to manage an incident are often hosted by the supplier that is having the incident. Many teams discovered that their incident bridge, their contact list and their runbook all lived in Teams and SharePoint.
During an outage: the first hour
- ConfirmCheck the provider's status and your own independent checks; rule out a local fault
- SwitchMove incident coordination to your out-of-band channel
- AssessList which critical services are affected and how badly
- WorkaroundApply pre-agreed workarounds, such as phone lines and alternative sign-in
- CommunicateTell staff and customers through channels that still work
- RecordNote times, impact and decisions for credits, regulators and the review
Avoid well-meant improvisation: staff forwarding company email to personal accounts, sharing files through unapproved tools or resetting passwords repeatedly. Outages are also a favourite moment for phishing that imitates the supplier's status messages, so warn staff to expect it.
Before the next one: the playbook
1. Map your dependencies. For each critical business process, list what it needs from the suite: email, chat, documents, identity, AI. Most organisations find identity is the biggest single point of failure, because it gates access to everything else.
2. Build an out-of-band channel and use it. Pick a messaging and paging tool from a different provider, with accounts for incident leaders, and use it for routine on-call so it works when needed.
3. Keep critical information outside the suite. Contact lists, escalation paths and top runbooks should exist somewhere that does not depend on it: a separate tool, an offline copy and a short printed card for on-call staff.
4. Plan emergency access. Keep a small number of monitored break-glass accounts that can reach critical systems if the main identity provider is unavailable, protected with hardware keys and tested regularly.
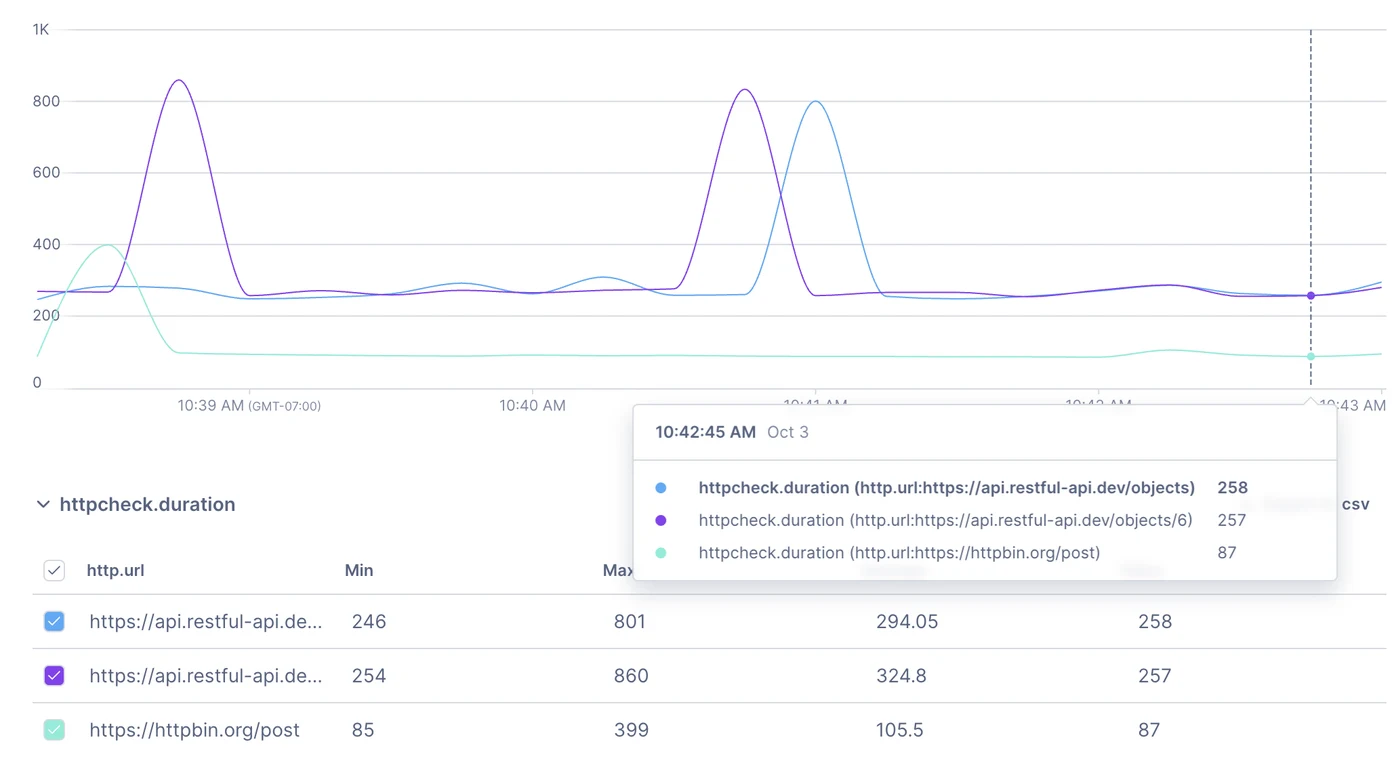
5. Detect independently. Do not rely on the supplier's status page or staff complaints. Simple synthetic checks against sign-in, mail and chat endpoints, run from outside your network, give you earlier warning and your own evidence6.
6. Give customers another route. A status page hosted elsewhere, SMS templates and a phone line mean customers hear from you even when email is down.
7. Decide what AI is allowed to be critical for. If teams rely on an AI assistant for routine work, decide what happens when it is unavailable, and make sure nothing that must happen depends on it alone.
8. Rehearse. Run a short exercise: "the suite is down for a day". It will expose gaps faster than any document review.
You cannot stop a supplier's outage. You can make sure it is an inconvenience rather than a crisis, by deciding in advance how you will talk, decide and serve customers without it.
Should you diversify away from one suite?
| Option | Benefit | Cost |
|---|---|---|
| Stay on one suite, add fallbacks | Simple, cheap, covers most risk | Fallbacks must be maintained and used |
| Separate identity provider | Sign-in survives a suite outage | More integration and licences |
| Second suite for critical teams | Full capability during outages | Expensive and confusing day to day |
For most organisations, the first option, with careful attention to identity and emergency access, gives the best return. Regulated firms with strict recovery targets may need more; see the Singapore insurer case study and the AI provider resilience case study.
This week
- Hold a 30-minute review: what stopped, what you improvised, what you would do differently.
- Record the incident IDs and your impact, and decide whether to claim service credits.
- Set up an out-of-band channel for incident leaders if you do not have one.
- Export critical contact lists and runbooks to a location outside the suite.
- When Microsoft's post-incident report is published, read it and update your plan.
CTO take
This outage was not a security incident, and it will be fixed. Its lasting value is as a free rehearsal: it showed every organisation exactly where it depends on one supplier, at no cost beyond a lost day. Use that evidence now, while people remember it, to fund the small fallbacks that turn the next outage into an inconvenience. Read alongside the 13 November tech news and SLOs and error budgets for small teams.
How I can help
I help organisations map critical dependencies, design fallbacks and emergency access, and run outage exercises that leave a plan people actually use. I am based in India, the United States and the UAE, working globally. See fractional CTO work, where I work, or analyse your challenge and bring the result to a call.
- 1Massive Microsoft 365 outage disrupts Outlook, Teams, Copilot worldwideBleepingComputer · 12 Nov 2026
- 2Microsoft 365 Outage Disrupts Outlook, Exchange Online and TeamsSecurityWeek · 12 Nov 2026
- 3Microsoft's major outage drags on, leaving Outlook, Teams, OneDrive, and other services still downXDA Developers · 12 Nov 2026
- 4Microsoft outage hits users worldwide, affecting Teams, Outlook and CopilotABC News · 13 Nov 2026
- 5
- 6Portable Synthetic HTTP Testing with OpenTelemetryOpenTelemetry blog · 5 Oct 2023